What is fractal image compression?
Most image formats store a description of the pixels. Fractal compression stores a description of how the picture resembles itself, and lets the decoder rebuild the pixels from that.
A JPEG file divides a photograph into small squares and records, for each square, which smooth patterns of light and dark add up to it. A PNG file records the pixels themselves, packed so that repetitions take less space. Both describe the picture directly.
A fractal file works differently. For every small part of the picture it records which larger part of the same picture looks similar, and how that larger part must be shrunk and adjusted to match. It contains no pixels at all. The picture is what you get when you follow these instructions over and over.
A picture that describes itself
Look at a photograph of rocks at the edge of a lake. The texture of one rock resembles the texture of another. A dark crack in one boulder looks much like a larger crack elsewhere, reduced. The line where water meets stone repeats with variations along the whole shore. Natural pictures are full of such approximate repetitions at different sizes.
The encoder exploits this in three steps:
- It divides the picture into small square blocks, called range blocks. In FIF2 they are between 4 and 32 pixels wide, smaller where the picture is busy and larger where it is calm.
- For each range block it searches the picture for a square twice as large, called a domain block, that looks like the range block once it is shrunk to half its size. The domain block may also be rotated or mirrored in one of eight ways.
- It records only the result of the search: where the domain block is, which of the eight orientations to use, how strongly to scale its contrast, and which brightness to give the result.
Written as a formula, the instruction for one range block R is
D is the domain block after shrinking and turning, D̄ its mean brightness, s the contrast factor and b the brightness of the result. The FIF2 encoder keeps the contrast factor smaller than one in magnitude. This one condition is what makes the method work.
How the picture comes back
The decoder receives the instructions but not the picture they refer to. It has nothing to copy from. It solves this by starting with a rough picture and applying all instructions to it at once: every range block is replaced by the shrunk and adjusted copy of its domain block, taken from the current picture. The result is a new picture. The decoder then applies the instructions to that one, and repeats.
Each round, every copy is reduced in size and its contrast is reduced by the factor s. Differences between the current picture and the true one are therefore reduced too, round after round, until the picture no longer changes. Mathematicians call a map with this property a contraction, and the picture it settles on its fixed point or attractor. The fixed point does not depend on where the decoder starts. Any starting picture leads to the same result; a good one only gets there sooner.
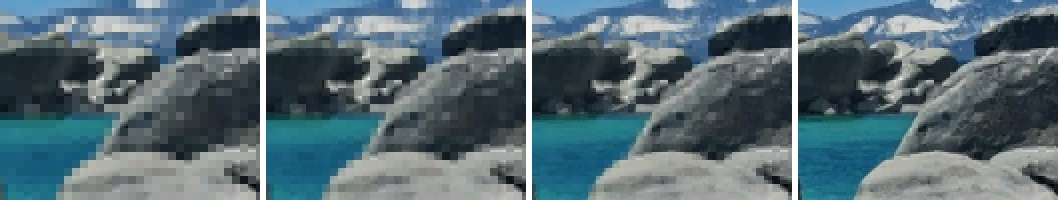
--relaxation 0.25)
so that the stages are visible; a normal decode converges in about ten
rounds.Why the encoder does not need the decoder
The encoder chooses each instruction by comparing the range block with a domain block from the original picture. The decoder applies the same instruction to its own picture, which is only an approximation. Why should the result still be close to the original?
The answer is a theorem that Michael Barnsley and his colleagues proved in 1986, the collage theorem. Suppose every range block, built from the original picture by its instruction, is close to the original range block. Then the attractor of all instructions is also close to the original picture. How close depends on the contrast factors: the further they stay below one, the smaller the gap between the collage and the attractor.
The encoder can therefore work on one block at a time and does not have to run the decoder. It controls the error of the final picture indirectly, through the error of each block.
What “fractal” means here
The word suggests the famous computer-generated shapes such as the Mandelbrot set or Barnsley's fern, in which every part is an exact reduced copy of the whole. Photographs are not like that. A rock does not contain exact smaller rocks. Fractal image compression uses only the weaker property that parts of a picture are approximately similar to other, larger parts after reduction and adjustment of brightness and contrast.
The name refers to the mathematics, not to the look of the result. The decoded picture is an attractor of a system of self-mapping transformations, the same kind of object as a mathematical fractal. It looks like a photograph because the encoder chose the transformations to reproduce one.
What follows from this
Because the file contains instructions instead of pixels, a few properties follow that ordinary formats do not have. The instructions refer to positions relative to the picture, not to a pixel grid, so the decoder can carry them out at a higher resolution than the original. The mean brightness of each block is stored separately from the fine structure, so a file can be read in two stages, coarse first. And the work is unevenly divided: finding good domain blocks is expensive, following the instructions is cheap. The next page describes these properties in detail, and where they end.